
Research article · 2020 · Full text
International Journal of Statistics and Applied MathematicsSingular value decomposition and principal component analysis: Misconceptions and disparities
Volume 5(1) · Pages 39–50
Research areasStatistical Methods and Applications
Abstract
Author-writtenThe application of singular value decomposition to perform principal component analysis is becoming increasingly evident in certain areas such as machine learning. The objective of this study is to differentiate these methods by clearly elucidating the disparities that exist theoretically and empirically. The study discovered that the PCA method is a product of the Eigen decomposition applied to the covariance/correlation matrix while SVD is achieved via a direct application to the dataset matrix after normalization. This was verified by carrying out a comparative analysis of both methods on a dataset consisting of standing heights and physical attributes (one dependent variable and seven independent variables) of 33 females applying for police officer positions in Akwa ibom state. The analysis was done using a MATLAB software program. The final results from the outputs obtained for both methods were the same. The study concluded that both methods are products of matrix decompositions and can be used to achieve the purpose of data reduction but the difference lies in how they are being applied.
Summary
Source-checkedPlain-language reading of the full paper, prepared with AI and checked against the text. Each point links to the authors' own words.
Why it matters
- Singular value decomposition (SVD) is increasingly used to perform principal component analysis (PCA), particularly in fields like machine learning. View evidence ↗
- PCA serves as a multivariate tool designed to reduce the dimensionality of high-dimensional datasets while preserving most of the original information. View evidence ↗
- Despite their importance, applications of linear algebra tools like SVD and PCA have sometimes been erroneous, necessitating a clearer understanding of their differences. View evidence ↗
The question
- The study aims to differentiate SVD and PCA by clarifying the theoretical and empirical disparities between the two methods. View evidence ↗
What they did
- The researchers performed a comparative analysis using a dataset of physical attributes and standing heights from 33 female police applicants. View evidence ↗
- The dataset used for the analysis consisted of seven independent variables and one dependent variable. View evidence ↗
- The comparative analysis of the two methods was executed using MATLAB software. View evidence ↗
What they found
- The study found that PCA relies on Eigen decomposition of a covariance or correlation matrix, whereas SVD is applied directly to a normalized dataset matrix. View evidence ↗
- Empirical testing showed that both the PCA and SVD methods produced identical final results. View evidence ↗
- The study demonstrated that PCA eigenvalues can be derived by squaring the singular values obtained from SVD. View evidence ↗
What it means
- The authors conclude that while both SVD and PCA are matrix decomposition tools effective for data reduction, they differ fundamentally in their application process. View evidence ↗
- The authors state that the primary disparity is that PCA requires a square symmetric covariance matrix for eigen decomposition, while SVD operates directly on the normalized data matrix. View evidence ↗
Visual summary
1 visualsIllustrations explain the paper; they do not show study data.
Workflow Comparison: PCA vs SVD
AI-generated conceptual illustration (Abstract mathematical data matrices and geometric transformations). It explains the idea and does not show study data.
View source evidence ↗Figures & tables
From the original paper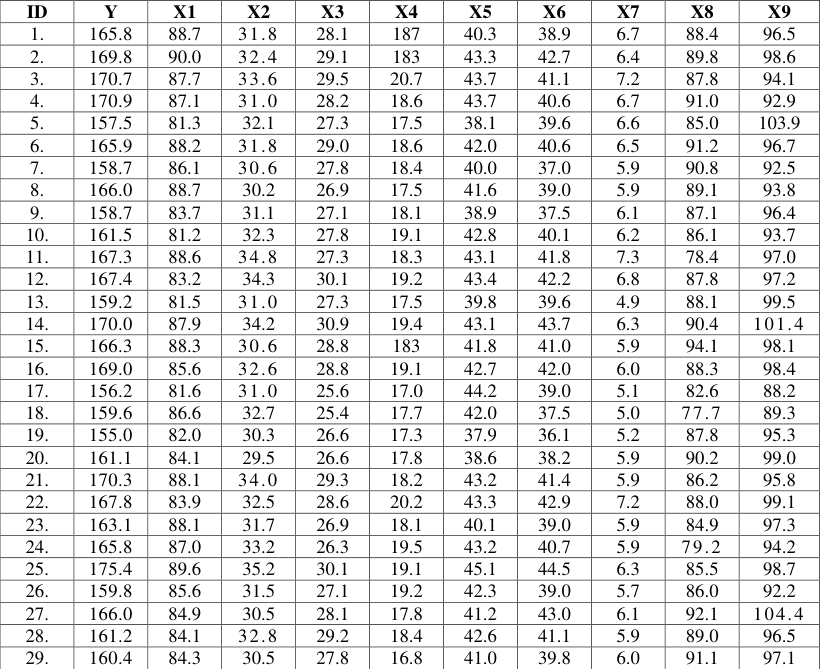 Table 1
Introduction
Mathematical methods tend to evolve on a daily basis. Due to the high demand of mathematical applications to technological innovations and virtually all aspect of human endeavor, the frontiers of mathematics have been stretched beyond expectations. The aforesaid is largely evident in linear algebra where applications from this area has been quite erroneous. Such ground-breaking outcomes of linear algebra are the singular value decomposition and principal component analysis. This research presents misconceptions and disparities on singular value decomposition and principal component analysis, and it is organized as follows: Introduction, development of singular value decomposition and principal component analysis are presented in Section Two. Comparative analysis of both singular value decomposition and principal component analysis with their in-depth structures are presented in Section Three, whereas results and discussions are presented in Section Four. Section five presents the concluding remark.
Development of singular value decomposition and principal component analysis
Singular value decomposition can be traced back to 1873 where it was first captured in a publication on bilinear forms by a mathematician called Eugenio Beltrami. A year after Beltrami's publication, Camille Jordan made another related publication on SVD but his accentuated the concept and made it more appealing to students for use. These two authors are considered co-discoverers of the singular value decomposition method. According to Gibiansky (2013) [5] , one of the best results of linear algebra is the decomposition method called singular value decomposition method. It is considered the highlight of linear algebra as it amplifies the inner structure of a matrix and produces the orthonormal bases for the four fundamental subspaces (column, left null, row and null spaces). It can be simply defined as the factorization of a matrix into the product of three matrices. That is, the SVD of a matrix B (m×n) is given as,
𝐵 = 𝑈Σ𝑉
Where 𝑈 is an m×m unitary matrix?
𝑉 Is an n×n unitary matrix Σ Is a diagonal matrix with non-negative real numbers on the diagonal.
The SVD generalizes the unitary transformation of a vector space which diagonalizes a linear transformation to the case of nonsquare matrices. The unitary transformations are special, because they preserve the l2-norm between the differences of any two vectors in a space they act upon. Unitary transformations preserve the l2-norm 'length' of any vector in the space. Unitary transforms preserve the eigenvalues of a linear transformation and preserve the kernel and the co-domain of the linear transformations they act upon.
Over time, the SVD method evolved into a robust technique with a wide-range of applications. From providing solutions to least square problems; numerical determination of the rank of a matrix, solutions of over determined system to principal component analysis in Statistics, the applications of SVD has become inexhaustible. However, the focus of interest of this paper is on the principal component analysis and how it distinguishes from SVD.
The principal component analysis is a multivariate analysis tool used to reduce a high multidimensional dataset to a low multidimensional dataset without much loss of information. PCA was first applied by Karl Pearson in 1901 though it was further developed by Harold Hotelling in 1930s. Geometrically, PCA is achieved by a rotation of the axes of the original coordinate system to new orthogonal axes, called principal axes, such that the new axes coincide with directions of the maximum variation of the original observations. The first component, which would lie in the direction of the maximum direction, accounts for the most variation while the second component, which lies in an orthogonal direction to the first, accounts for the second most variation of the data set and so on. With this kind of rearrangement of the dataset, a new set of variables can be obtained which makes it easier to select fewer set of variables for the data analysis without much loss of information. Basically, principal component analysis is performed by the Eigen decomposition of a data covariance or correlation matrix. It is at this point that the connection between these methods can be established given the fact both methods employ some form of matrix decomposition.
In an effort to simply lay the foundation for the extensions and generalization of SVD with respect to PCA, Cadima & Jollife, (2009) [2] described PCA as a singular value decomposition of a column-centered data matrix. Some applications do not want its data to be processed beforehand as the un-centered data is subjected to SVD. This is termed un-centered PCA. The paper considers the existing relationship between the results from SVD and PCA. Additionally, classical PCA is hinged on covariance/correlation decomposition matrix (Geladi & Kowalski, 1986) [4] by eigen-value (spectral) decomposition of real data matrices using SVD (Wall, Dyck, & Brettin, 2001) [8] .
Although compared with EVD, SVD is a more precise, robust and reliable methodology with no need to compute the input correlation/covariance matrix according to Will (1999) [9] . Classical PCA is not useful when the figure of variables is bigger than the observed number on each variable. In microarray data analysis, Lim, (2013) encountered this situation commonly when genes are accepted as the variables. In such instances, it is pertinent to use PCA using SVD (Deshunk & Purohit, 2007) [3] . For applying PCA using SVD, the DNA microarray data was in use for the small round blue cell tumors (SRBCT) of childhood by (Khan, et al., 2001) [7] . However, PCA and SVD have discovered wide-ranging tools. Here we define several studies that may infer potential strategies to employ for applications of these methods.
A study by Aremu, Adebayo, Ariyo, & Adewale (2007) [1] jointly applied PCA, single linkage cluster analysis and canonical analysis in identifying characters responsible for variation in Cowpea. These methods were effective in showing most distant accessions as having widest variation and possible choice of parent stocks in hybridization. Anand, et al., (2018) reviewed the singular value decomposition (SVD) framework and its use in quantifying and discerning vertical information in green house from column integrated absorption measurements. Bayesian optimal estimation (OE) assumes a prior distribution in order to regularize the inversion problem, while the SVD approach identifies principal components that can be retrieved from the measurement without explicitly specifying a prior mean and prior covariance. Anand et al, (2018) made a vital connection between the SVD method and the pseudo-inverse which intuitively makes it easy to understand. Zheng, Nie, & Ding (2018) [10] presented a stretched insight to the application of SVD by regularization. This regularized SVD, which is simply abbreviated as RSVD, is considered computationally efficient as it is non-convex and has a closed form global solution. It was applied to a recommender system and the result showed that RSVD was more efficient compared to SVD.
Comprehensive analysis
A comparative analysis was conducted on a dataset consisting of standing heights and physical attributes of 33 females applying for police officer positions. Seven (7) independent variables and 1 (one) dependent variable were collected and they are given as follows: In clearly delineating the disparities that exist between the PCA and SVD methods, it is imperative to go over the diagonalization of matrices and how the deficiencies in the eigen decomposition of matrices is being augmented by SVD.
A matrix A is diagonalizable if it can be written as a product such as
Where 𝐸 is a matrix that can be inverted and 𝐷 is a diagonal matrix. Seemingly, since 𝐸 is invertible then it must be square. It follows that a non-square matrix cannot be diagonalized as this idea seems unreasonable in this context. If equation ( 1) holds then 𝐴𝐸 = 𝐸𝐷, then 𝐸 is defined through its columns b i and 𝐷 via its diagonal entries;
Due to the way matrix multiplication works, each non-zero element in 𝐷 simply picks out a different column in 𝐸 and scales it. Hence,
What we can draw from this is that since 𝐴𝐸 = 𝐸𝐷, and we can consider the columns of 𝐸 separately from each other, the columns of 𝐸must be the eigenvectors of A and the values on the diagonal must be eigenvalues of A. (Since 𝐸is invertible, the space spanned by the eigenvectors must be the entire vector space, so the eigenvectors actually form a basis. Not all matrices are diagonalizable, since clearly not all matrices have eigenvectors that form a basis!) Given an 𝑚 × 𝑛 matrix 𝑋 for the dataset where the samples are the n columns (e.g. observations) and the m rows are variables, the objective is to transform the matrix 𝑋 linearly to another matrix 𝑌 of similar dimension 𝑚 × 𝑛. Hence, for some 𝑚 × 𝑚 matrix 𝑃, the PCA is given as
The matrix 𝑃 is a transformation matrix (the Eigen vectors of the data matrix) which is expected to change the basis from 𝑋 to 𝑌. Geometrically, 𝑃 is a rotation and a stretch which moves 𝑋 to 𝑌.
In some sense, the singular value decomposition is essentially diagonalization in a more general sense. The singular value decomposition plays a similar role to diagonalization, but it fixes the flaws we just talked about; namely, the SVD applies to matrices of any shape. Not only that, but the SVD applies to all matrices, which makes it much more generally applicable and useful than diagonalization! For the SVD we begin with an arbitrary real 𝑚 × 𝑛 matrix A. As we shall see, there are orthogonal matrices U and V and a diagonal matrix, this time denoted Σ, such that A = UΣV T . In this case, U is 𝑚 × 𝑚 and V is 𝑛 × 𝑛, so that Σ is rectangular with the same dimensions as A. The diagonal entries of Σ, that is the Σ ii = σ i , can be arranged to be nonnegative and in order of decreasing magnitude. The positive ones are called the singular values of A. The columns of U and V are called left and right singular vectors, for A.
The analogy between the EVD for a symmetric matrix and SVD for an arbitrary matrix can be extended a little by thinking of matrices as linear transformations. For a symmetric matrix A, the transformation takes ℛ 𝑛 to itself and the columns of V define an especially nice basis. When vectors are expressed relative to this basis, we see that the transformation simply dilates some components and contracts others, according to the magnitudes of the eigenvalues (with a reflection through the origin tossed in for negative eigenvalues). Moreover, the basis is orthonormal, which is the best kind of basis to have. Now let's look at the SVD for an 𝑚 × 𝑛 matrix A. Here the transformation takes ℛ 𝑛 to a different space, ℛ 𝑚 , so it is reasonable to ask for a natural basis for each of domain and range. The columns of V and U provide these bases. When they are used to represent vectors in the domain and range of the transformation, the nature of the transformation again becomes transparent: it simply dilates some components and contracts others, according to the magnitudes of the singular values, and possibly discards components or appends zeros as needed to account for a change in dimension. From this perspective, the SVD tells us how to choose orthonormal bases so that the transformation is represented by a matrix with the simplest possible form, that is, diagonal. How do we choose the bases
for the domain and range? There is no difficulty in obtaining a diagonal representation. For that, we need only Av i = σ i u i , which is easily arranged. Select an orthonormal basis A T A for ℛ 𝑛 so that the first k elements span the row space of A and the remaining n-k elements span the null space of A, where k is the rank of A. Then for 1 ≤ i ≤ k define u i to be a unit vector parallel to Av i , and extend this to a basis for ℛ 𝑚 . Relative to these bases, A will have a diagonal representation. But in general, although the v's are orthogonal, there is no reason to expect the u's to be. The possibility of choosing the v-basis so that its orthogonality is preserved under A is the key point. We show next that the EVD of the n×n symmetric matrix A T A provides just such a basis, namely, the eigenvectors of A T A. Let A T A = VDV T , with the diagonal entries λ i of D arranged in non-increasing order, and let the columns of V (which are eigenvectors of A T A) be the orthonormal basis
So the image set {Av 1 , Av 2 ,•••,Av n } is orthogonal, and the nonzero vectors in this set form a basis for the range of A. Thus, the eigenvectors of A T A and their images under A provide orthogonal bases allowing A to be expressed in a diagonal form.
To complete the construction, we normalize the vectors Av i . The eigenvalues of A T A again appear in this step. Taking i = j in the calculation above gives |Av i | 2 = λ i , which means λ i ≥ 0. Since these eigenvalues were assumed to be arranged in non-increasing order, we conclude that λ 1 ≥ λ 2 ≥•••≥λ k ≥ 0 and, since the rank of A equals k, λ i = 0 for i > k. The orthonormal basis for the range is therefore defined by
If k < m, we extend this to an orthonormal basis for ℛ 𝑚 . This completes the construction of the desired orthonormal bases for ℛ 𝑛 and ℛ 𝑚 . Setting σ i =√λ i we have Av i = σ i u i for all i ≤ k.
Assembling the v i as the columns of a matrix V and the u i to form U, this shows that AV = UΣ, where Σ has the same dimensions as A, has the entries σi along the main diagonal, and has all other entries equal to zero. Hence, A = UΣV T , which is the singular value decomposition of A.
In summary, an 𝑚 × 𝑛 real matrix A can be expressed as the product UΣV T , where V and U are orthogonal matrices and Σ is a diagonal matrix, as follows. The matrix V is obtained from the diagonal factorization A T A = VDV T , in which the diagonal entries of D appear in non-increasing order; the columns of U come from normalizing the non-vanishing images under A of the columns of V, and extending (if necessary) to an orthonormal basis for ℛ 𝑚 ; the nonzero entries of Σ are the respective square roots of corresponding diagonal entries of D.
The preceding construction demonstrates that the SVD exists, and gives some idea of what it tells about a matrix. There are a number of additional algebraic and geometric insights about the SVD that are derived with equal ease. The SVD encapsulates the most appropriate bases for the domain and range of the linear transformation defined by the matrix A.
There is a beautiful relationship between these bases and the four fundamental subspaces associated with A: the range and null space, and their orthogonal complements To relate SVD to PCA, there exists a theorem from linear algebra which stipulates that the non-zero singular variables of A are the nonzero eigenvalues square roots of AA T or A T A. The first assertion for the A T A case is proven in the succeeding way:
We note that A T A is same as Σ T Σ, and hence it has similar eigenvalues. Since Σ T Σ is a (𝑚 × 𝑚) square, diagonal matrix, the eigenvalues are hence the entries done diagonally, which are the singular values squares. Note that the non-zero eigenvalues of individual covariance matrices, AA T and A T A are very identical.
It is imperative to note that an eigenvalue matrix decomposition, A T A has been carried out. Certainly, since A T A is symmetric which is an orthogonal diagonalisation and hence the eigenvectors of A T A are the V columns. This is pertinent in making the practical linking between the PCA and SVD of the X matrix, which comes up next.
Recalling the initial 𝑚 × 𝑛 data matrix, X, let us describe a new 𝑛 × 𝑚 matrix, Z:
Recalling that since the rows of X on m contained the samples of n data, we removed the average of the row from individual entries to ensure no mean existed across the rows. Hence, the new Z matrix, has columns without mean. Consider establishing the 𝑚 × 𝑚 matrix, Z T Z:
𝑋𝑋 𝑇 … (8) 𝑖. 𝑒. 𝑍 𝑇 𝑍 = Σ 𝑥 We observe that describing Z in this pattern ensures that Z T Z is similar to the X, Σ 𝑥 is the covariance matrix. From the foregoing, the main components of X (subject to be identified) are the Σ 𝑥 eigenvectors. Thus, if we carry out an individual value matrix decomposition of Z T Z, the main components will be the orthogonal matrix, V columns. The final step is to link the SVD of Z T Z back to the change of basis signified by equation ( 3): Y = PX We like to show the original data onto the principal component described direction. Having the relative V = P T , this is basically: Y = V T X If recovering the original data is what we wish to do, we basically compute (employing orthogonality of V): X = VY … (9)
Results and Discussion
A comparative analysis was carried out on data presented in 3.4406 0 0 0 0 0 0 0 0 0 2.4926 0 0 0 0 0 0 0 0 0 1.4174 0 0 0 0 0 0 0 0 0 1.0392 0 0 0 0 0 0 0 0 0 0.7500 0 0 0 0 0 0 0 0 0 0.6117 0 0 0 0 0 0 0 0 0 0.4283 0 0
Columns 10 through 18 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 Columns 19 through 27 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 Columns 28 through 33 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 0 PC = The outputs above were used to compare the PCA and SVD methods. First of all, a PCA was carried out by first normalizing the dataset. After normalization the covariance matrix was obtained and an eigen decomposition was done on the covariance matrix. Usually, the eigenvalue and eigenvector outputs are not sorted for MATLAB R2007b. Thus, a sorting command was used to reorder the eigenvalues and their corresponding eigenvectors in decreasing order. This plays a huge part during the data reduction process as can be done here. For example, using a cut-off of 5.00 and above for the eigenvalues, the first and second eigenvalues will be selected since their eigenvalues are 11.8379 and 6.2129. Hence, their corresponding eigenvectors will be chosen to obtain a new set of 2 variables to represent an initial set of 7 variables. Similarly, a PCA was achieved using the SVD. Although, the process is rather different as SVD employs a direct computation of the data matrix, PCA applies an eigen decomposition on a covariance matrix. In the same vein, the SVD is done firstly by normalizing the data matrix and named it Y. Subsequently, the [u, S, PC] = svd (Y) is implemented to obtain the product of three matrices. The PC matrix can be discarded as it is redundant for principal component analysis. However, the U and S represent the eigenvectors and singular value matrix sorted in decreasing order. Just as captured in equation …, the eigenvalues obtained in PCA can be derived from the vector of singular values (diagonal elements of the singular value matrix) by multiplying the vector of singular values by itself to give a vector of eigenvalues V. Hence, the results for SVD can be equated to that of PCA from the outputs of both methods.
Conclusion
Singular value decomposition and principal component analysis are two eigenvalue methods used to reduce a high dimensional dataset into fewer dimensions while retaining important information. The disparity clearly lies in how these methods are being applied. PCA is done via eigen decomposition of the covariance matrix. This is possible because the covariance matrix is square symmetric. While SVD is carried out on the matrix itself after normalization. This pontification was verified by the results of the PCA and SVD analysis.
Figures and tables from the paper
| ID | Y | X1 | X2 | X3 | X4 | X5 | X6 | X7 | X8 | X9 |
|---|---|---|---|---|---|---|---|---|---|---|
| 1. | 165.8 | 88.7 | 31.8 | 28.1 | 187 | 40.3 | 38.9 | 6.7 | 88.4 | 96.5 |
| 2. | 169.8 | 90.0 | 32.4 | 29.1 | 183 | 43.3 | 42.7 | 6.4 | 89.8 | 98.6 |
| 3. | 170.7 | 87.7 | 33.6 | 29.5 | 20.7 | 43.7 | 41.1 | 7.2 | 87.8 | 94.1 |
| 4. | 170.9 | 87.1 | 31.0 | 28.2 | 18.6 | 43.7 | 40.6 | 6.7 | 91.0 | 92.9 |
| 5. | 157.5 | 81.3 | 32.1 | 27.3 | 17.5 | 38.1 | 39.6 | 6.6 | 85.0 | 103.9 |
| 6. | 165.9 | 88.2 | 31.8 | 29.0 | 18.6 | 42.0 | 40.6 | 6.5 | 91.2 | 96.7 |
| 7. | 158.7 | 86.1 | 30.6 | 27.8 | 18.4 | 40.0 | 37.0 | 5.9 | 90.8 | 92.5 |
| 8. | 166.0 | 88.7 | 30.2 | 26.9 | 17.5 | 41.6 | 39.0 | 5.9 | 89.1 | 93.8 |
| 9. | 158.7 | 83.7 | 31.1 | 27.1 | 18.1 | 38.9 | 37.5 | 6.1 | 87.1 | 96.4 |
| 10. | 161.5 | 81.2 | 32.3 | 27.8 | 19.1 | 42.8 | 40.1 | 6.2 | 86.1 | 93.7 |
| 11. | 167.3 | 88.6 | 34.8 | 27.3 | 18.3 | 43.1 | 41.8 | 7.3 | 78.4 | 97.0 |
| 12. | 167.4 | 83.2 | 34.3 | 30.1 | 19.2 | 43.4 | 42.2 | 6.8 | 87.8 | 97.2 |
| 13. | 159.2 | 81.5 | 31.0 | 27.3 | 17.5 | 39.8 | 39.6 | 4.9 | 88.1 | 99.5 |
| 14. | 170.0 | 87.9 | 34.2 | 30.9 | 19.4 | 43.1 | 43.7 | 6.3 | 90.4 | 101.4 |
| 15. | 166.3 | 88.3 | 30.6 | 28.8 | 183 | 41.8 | 41.0 | 5.9 | 94.1 | 98.1 |
| 16. | 169.0 | 85.6 | 32.6 | 28.8 | 19.1 | 42.7 | 42.0 | 6.0 | 88.3 | 98.4 |
| 17. | 156.2 | 81.6 | 31.0 | 25.6 | 17.0 | 44.2 | 39.0 | 5.1 | 82.6 | 88.2 |
| 18. | 159.6 | 86.6 | 32.7 | 25.4 | 17.7 | 42.0 | 37.5 | 5.0 | 77.7 | 89.3 |
| 19. | 155.0 | 82.0 | 30.3 | 26.6 | 17.3 | 37.9 | 36.1 | 5.2 | 87.8 | 95.3 |
| 20. | 161.1 | 84.1 | 29.5 | 26.6 | 17.8 | 38.6 | 38.2 | 5.9 | 90.2 | 99.0 |
| 21. | 170.3 | 88.1 | 34.0 | 29.3 | 18.2 | 43.2 | 41.4 | 5.9 | 86.2 | 95.8 |
| 22. | 167.8 | 83.9 | 32.5 | 28.6 | 20.2 | 43.3 | 42.9 | 7.2 | 88.0 | 99.1 |
| 23. | 163.1 | 88.1 | 31.7 | 26.9 | 18.1 | 40.1 | 39.0 | 5.9 | 84.9 | 97.3 |
| 24. | 165.8 | 87.0 | 33.2 | 26.3 | 19.5 | 43.2 | 40.7 | 5.9 | 79.2 | 94.2 |
| 25. | 175.4 | 89.6 | 35.2 | 30.1 | 19.1 | 45.1 | 44.5 | 6.3 | 85.5 | 98.7 |
| 26. | 159.8 | 85.6 | 31.5 | 27.1 | 19.2 | 42.3 | 39.0 | 5.7 | 86.0 | 92.2 |
| 27. | 166.0 | 84.9 | 30.5 | 28.1 | 17.8 | 41.2 | 43.0 | 6.1 | 92.1 | 104.4 |
| 28. | 161.2 | 84.1 | 32.8 | 29.2 | 18.4 | 42.6 | 41.1 | 5.9 | 89.0 | 96.5 |
| 29. | 160.4 | 84.3 | 30.5 | 27.8 | 16.8 | 41.0 | 39.8 | 6.0 | 91.1 | 97.1 |
Table text extracted from the original PDF; superscript letters are shown inline. The original table image is below.
View original table image
References
10 in the original paper- Aremu CO, Adebayo MA, Ariyo OJ, Adewale BB. Classification of genetic diversity and choice of parents for hybridization in cowpea Vigna unguiculata (L.) Walp for humid savanna ecology. African Journal of Biotechnology. 2007; 6(20):2.
- Cadima J, Jollife IT. Variable selection and the interpretation of principal subspaces. J Agri. Biol. Environ. Statist. 2009; 6:6279.
- Deshunk SR, Purohit SG. Microarray Data, Statistical Analysis Usng R. Alpha Science International Ltd., 2007.
- Geladi P, Kowalski B. Partial Least Squares Regression. A Tutorial. Analytica Chimica Acta. 1986; 185:17.
- Gibiansky A. (May 29). Cool linear algebra. Retrieved from Andrew gibiansky, 2013. http://andrew.gibiansky.com/blog/mathematics/cool-linear-algebra-singular-value-decomposition/
- K AR, Hai MN, Xiaoli S, Jianping M, James BA, Jonathan MH et al. A Singular Value Decomposition framework for retrievals with vertical distribution information from greenhouse gas column absorption spectrosco, 2018.
- Khan J, Ringner M, Saal LH, Ladanyi M, Westermann F, Berthold F et al. Classification and diagnostic prediction of cancers using gene expression profiling and artific, 2001.
- Wall ME, Dyck PA, Brettin TS. SVDMAN-singular value decomposition analysis of microarray data. Bioinformatics. 2001; 17:566-68.
- Will T. Introduction to the singular value decomposition, 1999.
- Zheng S, Nie F, Ding C. Regularized Singular Value Decomposition and Application to Recommender system, 2018. Retrieved from https://arxiv.org/pdf/1804.0509.
Cited by 1
From OpenAlex, OpenCitations and reference lists read by Scinovex
- A new rapid positioning strategy for the impact-point using dynamic mode decomposition and time difference of arrival * ↗
Shengfan Bi, Yong Huang, Hao Eric Wang, Jinyu Zhao · Measurement Science and Technology · 2023
Abstract In outdoor shooting range experiments, locating the projectile impact point is typically done through manual search, which can be time-consuming and costly. To improve experimental efficiency and reduce costs, this paper proposes a new approach for localizing the impact point using the dynamic mode decomposition (DMD) extension method and time difference of arrival (TDOA) based on seismic waves. The…
❝ 2