
Research article · 2020 · Full text
International Journal of Statistics and Applied MathematicsTesting of hypothesis using the bayes factor
Volume 5(3) · Pages 32–36
Research areasAdvanced Statistical Methods and ModelsStatistical Methods in Clinical TrialsBayesian Modeling and Causal Inference
Abstract
Author-writtenIn any testing problem, the most popular procedure to draw a conclusion regarding the null and alternative hypotheses is to use the p-value of the test. If the p-value is below a certain level of significance “the test is rejected” and if not “we fail to reject the null hypothesis based on the observed data”. What if we wanted to know how much more favoured the alternative hypothesis was, based on the data observed, than the null hypothesis. The p-value only taking into account the distribution under the null setup fails to answer this question. This is primarily why we use the Bayes Factor. The purpose of this paper is to provide a brief overview of the Bayes Factor. Using two simple examples the use of Bayes Factor in testing problems is depicted and conclusions drawn. The paper tries to establish the Bayes Factor as another practical tool for testing of hypotheses.
Summary
Source-checkedPlain-language reading of the full paper, prepared with AI and checked against the text. Each point links to the authors' own words.
Why it matters
- The p-value is the most common method used to draw conclusions about null and alternative hypotheses in testing problems. View evidence ↗
- The Bayes Factor is derived from Bayes' theorem and allows for a relative comparison of the plausibility of two competing hypotheses. View evidence ↗
The question
- The paper aims to provide an overview of the Bayes Factor and demonstrate its use in hypothesis testing through two examples. View evidence ↗
What they did
- Prior odds are calculated as the ratio of the prior probabilities of the alternative hypothesis (H1) to the null hypothesis (H0). View evidence ↗
- Posterior odds represent the ratio of the probabilities of the two competing hypotheses after the relevant data has been examined. View evidence ↗
- The Bayes Factor is mathematically defined as the ratio of the posterior odds to the prior odds. View evidence ↗
- In the first example, a sample of 20 fluorescent lamps was tested for defects to evaluate a manufacturer's claim that no more than 30% are defective. View evidence ↗
- The second example uses the Statlog Dataset on Heart Failure to test if the average age of the first heart attack differs between men and women. View evidence ↗
What they found
- In the lamp example, the Bayes Factor for the null against the alternative (BF01) was 11.24671, assuming prior odds of 1. View evidence ↗
- The result for the lamp example indicates moderate evidence for the null hypothesis, suggesting the null is 11 times more likely than the alternative. View evidence ↗
- In the heart attack age example, the Bayes Factor (BF10) was 8.9233, meaning the alternative hypothesis is approximately 9 times more likely than the null. View evidence ↗
- The heart attack data provides moderate evidence that the mean ages for the first heart attack differ between men and women. View evidence ↗
- For the heart attack study, the posterior probabilities were calculated as 0.1008 for the null hypothesis and 0.8992 for the alternative hypothesis. View evidence ↗
What it means
- The authors conclude that the Bayes Factor is superior to conventional testing because it incorporates both prior probabilities of parameters and the likelihood of the data. View evidence ↗
- A significant limitation is that the Bayes Factor and the resulting conclusions are sensitive to the choice of the prior distribution; using non-informative priors can lead to incorrect hypothesis acceptance. View evidence ↗
Visual summary
1 visualsIllustrations explain the paper; they do not show study data.
Bayes Factor Conceptual Flow
AI-generated conceptual illustration (Abstract mathematical conceptualization of probability distributions). It explains the idea and does not show study data.
View source evidence ↗Figures & tables
From the original paper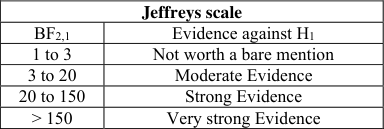 Table 1
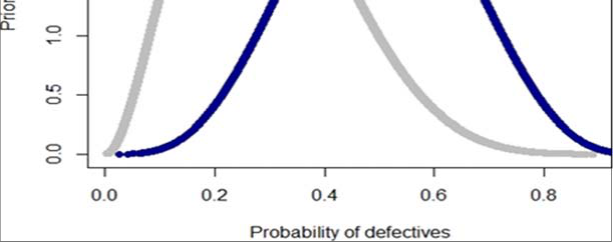 Figure 1
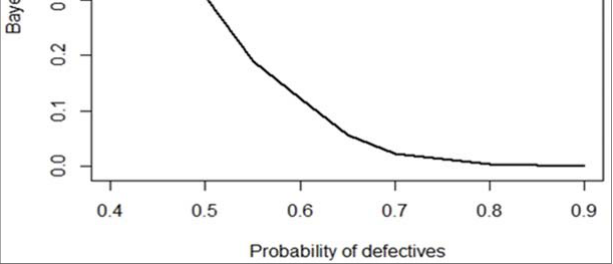 Figure 2
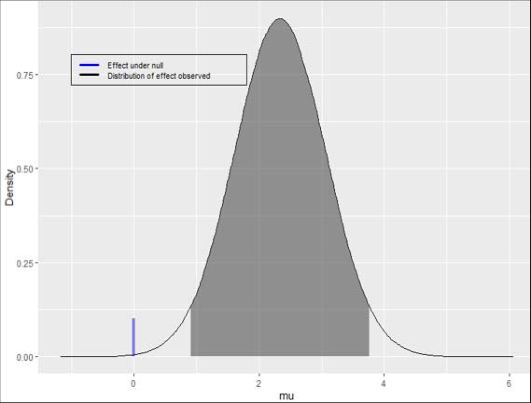 Figure 3
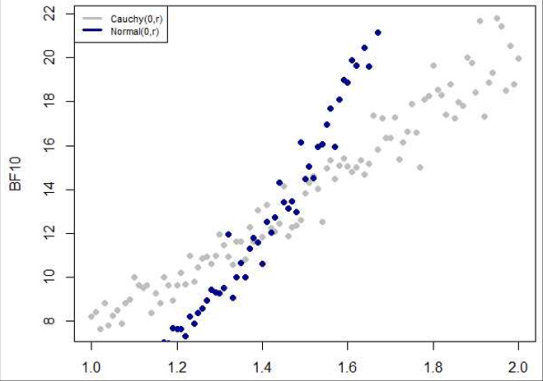 Figure 4
Introduction
The Bayesian approach uses a fully probabilistic framework to draw conclusions based on the observed data. Given a null and an alternative statistical model, Bayesian analysis uses the idea of Bayes theorem to compute the posterior probability of one of the models being better, in light of the observed data. The Bayes Factor is a straightforward consequence of the Bayes theorem that allows us to do just so, that is, compare the plausibility of the two competing hypotheses relatively. Intuitively, it can be regarded as the weight of evidence provided by the data in favour of one of the hypotheses. It is the ratio of the odds of observing two competing hypotheses after investigating relevant data compared to the odds of observing those hypotheses before investigating the data. The Bayes Factor for the alternative versus the null is a ratio comparing how likely the data is under the alternative model versus the null model. As the Bayes Factor in favour of the alternative increases, the probability of observing the alternative hypothesis increases, relative to the null. In case of a simple versus simple testing problem the Bayes Factor reduces to the likelihood ratio. For example, Let the hypotheses H1 and H2 be deemed equally probable a priori, that is p(H1)=p(H2)= 0.5. Then if the Bayes Factor in favour of the H2, BF2,1= 8, it means that after conducting the experiment, H2 is deemed eight times more likely than H1. Bayes Factor being a ratio of probabilities take values between 0 and infinity. If it is greater than 1 we conclude that the alternative model is more likely but a natural question now is how do we draw conclusions for the testing problem based on the value of the Bayes Factor? A commonly used scale for drawing conclusions is the Jeffreys scale (1961) [1]
Method of calculating the Bayes Factor
Let the null hypothesis be denoted by H0 and the alternative hypothesis be denoted by H1. Before the testing procedure is carried out it is assumed that prior probability of observing H0, or the prior probability of observing the parameter of interest under H0 is P(H0 ). Similarly the prior probability of assuming H1 is P(H1 ). We now define the prior odds and posterior odds. The prior odds is defined as ratio of observing the two hypotheses before examining the data. It is the ratio of the prior probabilities of the hypotheses H1 to H0. In mathematical terms, O10= P(H1)/P(H0).
Similarly, the posterior odds is the ratio of the odds of observing two competing hypotheses after examining relevant data written as PO10 = P(H1|data)/P(H0|data).
Using Bayes' the posterior odds can be written in terms of the prior odds as:
The Bayes Factor is the posterior odds in favour of one hypothesis when the prior probabilities on the two hypotheses are equal. Hence, the Bayes Factor is the ratio of posterior odds to prior odds.
Applications
The use of Bayes Factor is denoted using the following two examples.
Example 1.
Suppose a manufacturer of fluorescent lamps claims that no more than 30% of his products is defective. A sample of 20 lamps is found to contain 4 defective lamps. We need to obtain whether the manufacturer's claim is justified.
Here the null hypothesis is H0: p=0.3 and the alternative hypothesis H1: p>0.3.
We summarize this data using a Binomial(20, 4) likelihood function.. The Beta prior on p is appropriate to describe hypotheses as it is continuously defined on the interval between 0 and 1 and is not always symmetric. However looking at the value of p under null we need to choose a distribution which places the bulk of the probability density at or around 0.3. Therefore, we use a Beta (3,7 ) prior distribution to describe the null hypothesis. Similarly, we use a Beta (5,5) prior distribution to describe the alternative hypothesis as this skewed distribution places the bulk of the probability density at or around 0.5 (i.e., higher probability of defectives) and places less density on values less than 0.3.
Results
Assuming the prior odds to be 1 the Bayes Factor BF10 for H1 against H0 is 0.088914. As this value does not lie on Jeffrey's scale, we take the reciprocal of BF10, which is nothing but BF01, the Bayes Factor for Ho against H1. Taking the reciprocal BF01 is 11.24671.
Discussion
Thus we draw the conclusion that there is moderate evidence in favour of the null hypothesis. Based on the data the null seems 11 times as likely as the alternative hypothesis. Taking various prior Beta densities with increasing probabilities for defective items, as observed in Fig. 2, the Bayes Factor BF01 decreases. The null hypothesis becomes more and more likely given the data as the probability of defective items under the alternative increases (which is reasonable!).
Reiterating, as seen in the above example the Bayes Factor is sensitive to the choice of the prior distribution. As the parameters of the Beta prior vary, so does the Bayes factor! Nevertheless, there are a few default priors which give fairly good results in most cases one such being the Jeffrey-Zellner-Siow prior which is used in the next example.
Example 2.
Suppose we were given the values of the ages of having the first heart attack for a few people and we were required to test whether the average age for the first heart attack differed for men and women. The dataset used here is the Statlog Dataset on Heart Failure [15] .We calculate the mean age for women and denote it be by μwomen and that for men as μmen. Let the Null Hypothesis be denoted by H0 and the Alternative Hypothesis be denoted by H1..In mathematical terms we test H0: μwomen = μmen against the alternative H1: μwomen ≠ μmen.
We will view the data as a random sample from two populations, one for men and women. Let the total number of women=n1 and the total number of men=n2. The two groups are modeled as:
Xi∼N (μ+ε, σ 2 ) iid for all i=1(1) n1 Yi ∼N(με, σ 2 ) iid for all i= 1(1) n2
The model Xi stands for mean age of having the first heart attack for the i th woman and the model Yi stands for mean age of having the first heart attack for the i th man. It is assumed that the observations are independent and identically distributed, with means μ+ ε and μ-ε and variance σ 2 . Hence, the testing problem reduces to H0:2ε =0 ⇔H0:ε =0 (The means are not different) versus H1: ε ≠0(The means are different) To test the hypothesis, we require assumptions about prior distributions for ε, μ, σ 2 under both the hypotheses. For the continuous case, when the value of the parameter can take any value within a given range, the Bayes Factor is obtained by integrating over the entire range of the parameters under the models. In this case the Bayes Factor Under H0 we assume ε is degenerate at 0 and under H1 we use a Cauchy prior for ε. In Bayesian testing, the commonly used method is to use effect sizes (Cohen's d) to test the hypotheses. Effect sizes simplify comparison using the idea of plausibility of relative effects under the models. Here we use the standardized effect δ with the scale of r where δ= ε /σ 2 ∼Cauchy(0,r 2 ). In terms of effect sizes, under H0 gender is assumed to have no effect. Hence the entire probability of δ is concentrated at 0.Under the alternative model the effect size is assumed to take both positive and negative values with equal probability. Now, under both the hypotheses, we use the Jeffreys-Zellner-Siow (JZS) default prior for μ and σ 2 . As mentioned above the JZS prior does not vary much with the choice of hyperparameters in the prior distributions. It also simplifies the computation of the Bayes Factor. Here we assume prior probability of both hypotheses to be equal, that is P(H0) = 0.5 and P(H1) = 0.5
Method and material used
We use R to calculate the Bayes factor.
R code library(statsr) w=read.csv("C:/Users/ICLUSER/Desktop/Bookbayes.csv") bayes_inference(y=difference,data=w,type="ht",statistic="me an",alternative="twosided", null=0)
Results
Running the code we obtained the value of BF10=8.9233. That means the alternative is approximately 9 times as likely as the null set after examining the dataset. Therefore, based on the data we conclude that the mean ages for the first heart attack of men and women are not the same. There is moderate evidence that the mean ages are different for men and women.
Discussion
The posterior probabilities are obtained as P(H0|data) = 0.1008 and P(H1|data) = 0.8992. Thus we can estimate the likelihood of the posterior probability given the two models. This is another advantage of the Bayes Factor. The Bayes Factor helps us to compare between models in mathematical terms, using posterior probabilities.
. The above plot gives us the likelihood of the standardized effect size under the data which is depicted by the grey shaded region and the distribution of effect size under H0 which is assumed to be degenerate at 0.From the plot it can be concluded that the effect observed as given by the data set is far removed from the value zero. Therefore, on the basis of the data it could be concluded that the effect is highly unlikely to have a distribution which has the bulk of its probability concentrated at zero. As mentioned earlier, Bayes Factor is susceptible to the choice of the prior distribution. It varies according to the choice of the parameter r in our example. However under few priors the Bayes Factor is known to be fluctuate less. For example, if we had assumed the standardized effect followed a Normal prior instead of a Cauchy Prior then the Bayes Factor as seen in Fig. 4 would vary a lot more with the choice of the parameters of the prior distribution.
Conclusion
The advantage of the Bayes Factor over conventional methods of testing is that it incorporates information at all stages of the problem. It takes into account the prior probabilities of the parameters and includes the likelihood of the data as well. As opposed to the p-value which considers the distribution under the null only, it allows us to make a comparative study of the null and alternative distributions. Bayes factor assists in making conclusions regarding the unknown parameters of interest in concrete mathematical terms. It enables us to draw conclusion in terms of posterior and prior probabilities. However all of this can be done if prior distributions are carefully chosen. This requires some preconceived knowledge regarding the parameters, source of the data and the process of data collection.
Figures and tables from the paper
| Jeffreys scale | — |
|---|---|
| BF2,1 | Evidence against H1 |
| 1 to 3 | Not worth a bare mention |
| 3 to 20 | Moderate Evidence |
| 20 to 150 | Strong Evidence |
| > 150 | Very strong Evidence |
Table text extracted from the original PDF; superscript letters are shown inline. The original table image is below.
View original table image
References
14 in the original paper- Jeffreys H. Theory of Probability, Third Edition. Oxford University Press, 1961.
- Berger JO. Statistical decision theory and Bayesian analysis. Springer Science & Business Media, 2013.
- Jeon M, De Boeck P. Decision qualities of Bayes factor and p value-based hypothesis testing. Psychological Methods. 2017; 22(2):340-360.
- Berger JO, Pericchi LR. The intrinsic Bayes factor for model selection and prediction. Journal of the American Statistical Association. 1996; 91(433):109-122.
- Edwards W, Lindman H, Savage LJ. Bayesian statistical inference for psychological research. Psychological Review. 1963; 70(3):193-242.
- Quintana DS, Williams DR. Bayesian alternatives for common null-hypothesis significance tests in psychiatry: a non-technical guide using JASP. BMC Psychiatry. 2018; 18:178.
- Dienes Z. Using Bayes to get the most out of nonsignificant results. Front Psychol. 2014; 5(781):1-17.
- Kass RE. Bayes factors in practice. Journal of the Royal Statistical Society: Series D (The Statistician). 1993; 42(5):551-560.
- Florens JP, Mouchart M. Bayesian testing and testing Bayesians. Université Catholique de Louvain. Center for Operations Research and Econometrics [CORE], 1992.
- Kadane JB, Dickey JM. Bayesian decision theory and the simplification of models. In Evaluation of econometric models. Academic Press, 1980, 245-268.
- Aitkin Murray. "Posterior bayes factors." Journal of the Royal Statistical Society: Series B (Methodological). 1991; 53(1):111-128.
- Kass Robert E, Adrian E Raftery. "Bayes factors and model uncertainty, 1995.
- Jeffrey N, Rouder Richard, Morey D. Default Bayes Factors for Model Selection in Regression. Multivariate Behavioral Research. 2012; 47:877-903.
- Robert Kass E, Adrian Raftery E. Bayes Factors, Journal of the American Statistical Association. 1995; 90:430, 773-7953.